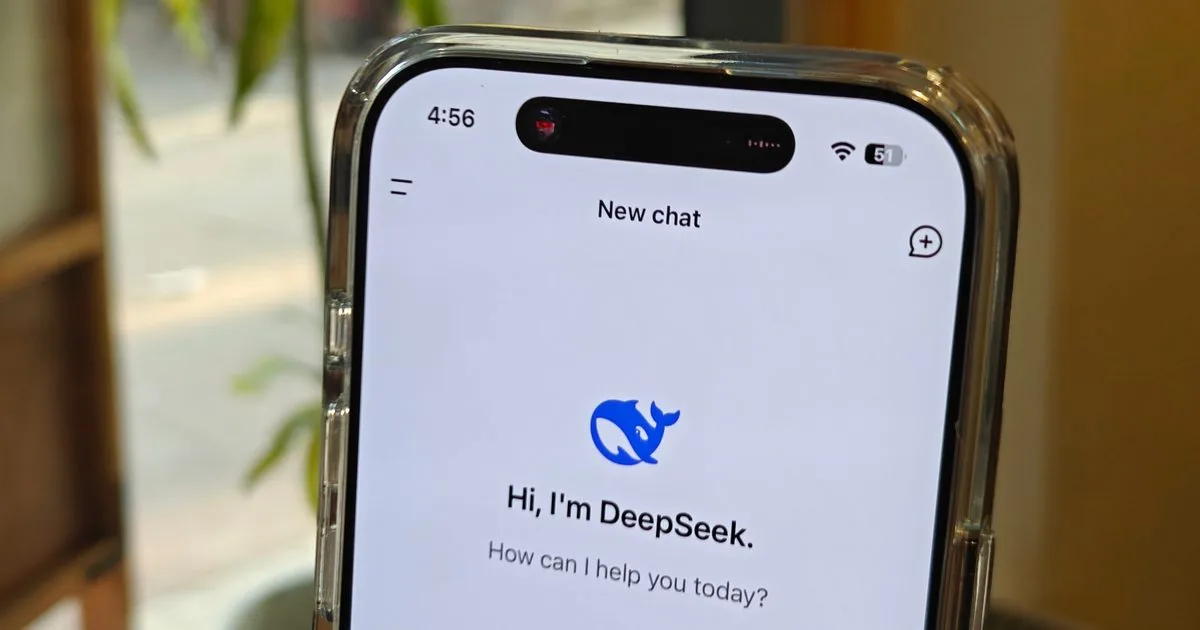
DeepSeek has officially launched its highly anticipated V4 preview, introducing two open-source AI models that aggressively challenge Silicon Valley's top-tier offerings. The release includes the massive 1.6-trillion-parameter DeepSeek V4-Pro and the highly efficient 284-billion-parameter V4-Flash. Both models feature a massive one-million-token context window, positioning them as formidable alternatives for developers seeking high performance without the exorbitant costs associated with proprietary models.
These models are fully open-source and available for download on Hugging Face, allowing developers to run them locally on their own hardware. However, deploying the V4-Pro model locally requires a substantial amount of VRAM due to its sheer scale. The V4-Pro operates with 49 billion active parameters, while the V4-Flash utilizes 13 billion active parameters, offering a balance between computational efficiency and advanced reasoning capabilities as announced on April 24, 2026.
Benchmark Dominance in Coding and Agentic Tasks
DeepSeek V4-Pro delivers exceptional results in competitive programming and agentic workflows. On the Codeforces benchmark, V4-Pro scores an impressive 3,206, surpassing GPT-5.4's 3,168 and Gemini 3.1's 3,052. This establishes it as the strongest open-source model currently available for complex coding tasks. Furthermore, it achieves a 93.5 on LiveCodeBench, comfortably beating Claude Opus 4.6, and scores 51.8 on Toolathlon for agentic tasks.
| Benchmark | DeepSeek V4-Pro | Claude Opus 4.6 | GPT-5.4 | Gemini 3.1 Pro |
|---|---|---|---|---|
| Codeforces (Rating) | 3,206 | - | 3,168 | 3,052 |
| LiveCodeBench (Pass@1) | 93.5 | 88.8 | - | 91.7 |
| Apex Shortlist (Pass@1) | 90.2 | 85.9 | 78.1 | 89.1 |
| SWE Verified (Resolved) | 80.6 | 80.8 | - | 80.6 |
| Toolathlon (Pass@1) | 51.8 | 47.2 | 54.6 | 48.8 |
| Terminal Bench 2.0 (Acc) | 67.9 | 65.4 | 75.1 | 68.5 |
| MRCR 1M Long Context | 83.5 | 92.9 | - | 76.3 |
| HMMT 2026 Math | 95.2 | 96.2 | 97.7 | 94.7 |
| IMOAnswerBench | 89.8 | 75.3 | 91.4 | 81.0 |
Despite its coding prowess, DeepSeek V4-Pro still trails behind its American competitors in specific areas. Anthropic's Claude Opus 4.6 maintains a clear lead in long-context retrieval, scoring 92.9 on the MRCR 1M benchmark compared to V4-Pro's 83.5. Additionally, OpenAI's GPT-5.4 continues to dominate terminal-based operations, scoring 75.1 on Terminal Bench 2.0 against V4-Pro's 67.9.
Forcing a Market Correction in Enterprise AI Pricing
The true disruption of DeepSeek V4 lies in its aggressive pricing strategy. At just $3.48 per million output tokens, V4-Pro drastically undercuts the industry standard, where equivalent workloads cost $30 with OpenAI and $25 with Anthropic. This massive price gap fundamentally alters the economics for developers building AI-powered applications.
By offering top-tier coding performance at nearly a tenth of the cost, DeepSeek is forcing a market correction that will likely pressure Western AI labs to reevaluate their enterprise pricing structures. For startups and independent developers, the ability to leverage a 1-million-token context window at this price point removes one of the biggest financial barriers to scaling generative AI tools.
This article was written by AI from reporting by digitaltrends.com.