Retrieval augmented generation (RAG) is a way of answering questions with a large language model (LLM) in which an application first searches its own documents for text related to the question and sends that text to the model along with the question. The model then answers from the provided data instead of from what it remembers. A demo application built in plain Java 17 illustrates this by answering questions about private recipes, running entirely locally with no API key. It uses a small embedding model from LangChain4j to turn recipe text into searchable numbers, and a small model running in Ollama to write the answer. In testing, without RAG, the model guesses the baking time of a lemon cake and gets it wrong, but with RAG, it reads the recipe first and answers correctly.
Why an LLM Doesn't Know Your Documents
An LLM knows only the public text it was trained on. Private documents, such as a company wiki or a family recipe file, were never part of its training, leaving the model with nothing to look up when asked about them. Instead of stating its lack of knowledge, it produces the answer that sounds most likely.
For example, a family recipe file for Nani's Lemon Semolina Cake instructs to bake the cake at 170 C for 38 minutes. When asking a small local model, qwen2.5:0.5b on Ollama, about it with no other text in the prompt, the result is incorrect:
Question: How long do I bake Nani's Lemon Semolina Cake, and at what temperature?

Answer: To bake Nani's Lemon Semolina Cake, you should bake it at 350°F (180°C) for 30 minutes.
The answer is wrong on both numbers, and nothing in it sounds unsure. RAG fixes this without retraining the model by handing it the right page of the documents with every question.
How Retrieval Augmented Generation Works in Three Phases
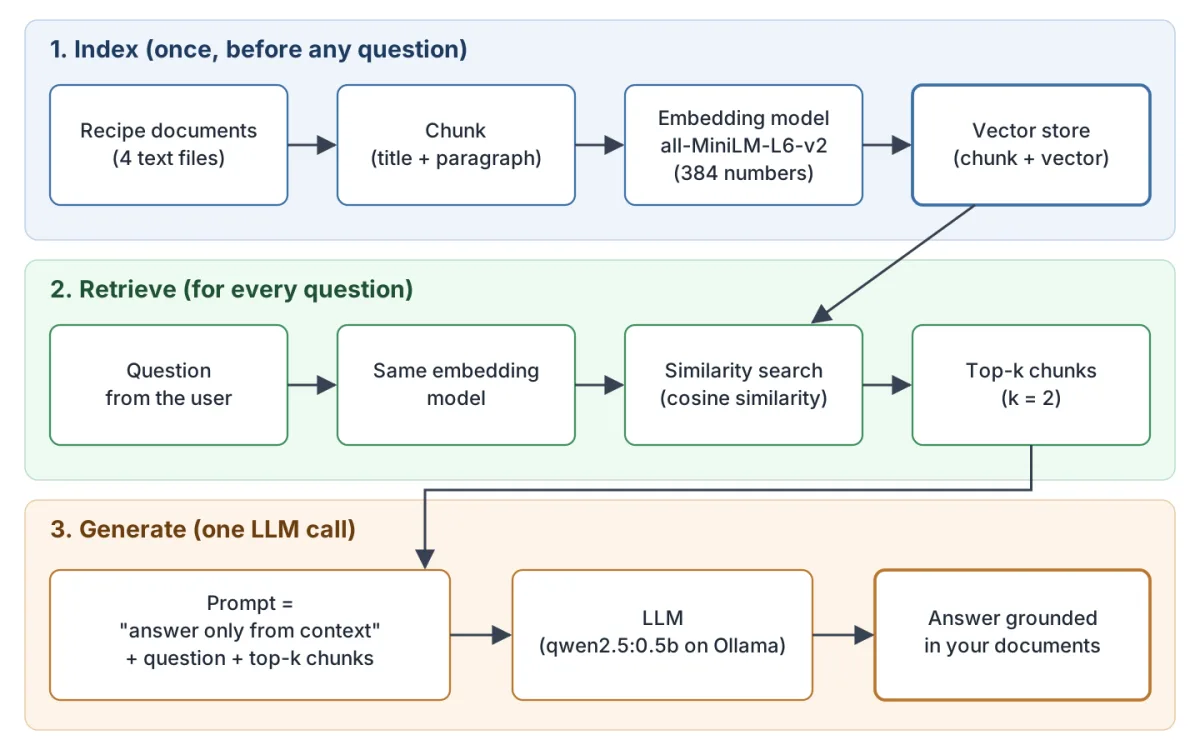
A RAG application runs in three phases. The first phase runs once before any question arrives, while the other two run for every question.
- Index: Every document is split into small pieces called chunks. Each chunk is turned into a list of numbers using an embedding model, and both the chunk and its numbers are saved in a vector store.
- Retrieve: When a question arrives, it is turned into numbers with the same embedding model. The vector store then returns the few chunks whose numbers are closest to the question's numbers.
- Generate: An instruction, the question, and the retrieved chunks are put into one prompt and sent to the LLM, which writes the answer.
The name follows these phases: text is retrieved, the prompt is augmented with it, and the model generates the answer. The index is built once, and every subsequent question runs one search and one LLM call. This structure is similar to an open-book exam where a helper finds the matching pages for a student who has never read the textbook.
Parts of a RAG Pipeline
A chunk is a piece of a document small enough to be about one thing, such as one paragraph of a recipe. Chunks are searched instead of whole documents because a whole document would fill the prompt with unnecessary text. A chunk should also make sense when read alone.
An embedding is an array of numbers (a float[] in Java) that represents the meaning of a text, produced by an embedding model. For example, if "bake the cake" becomes {0.9, 0.1} and "oven time for the cake" becomes {0.8, 0.2}, the arrays hold almost the same numbers because the texts mean almost the same thing. "Serve the soup hot" might become {0.1, 0.9}, which looks very different. The all-MiniLM-L6-v2 model works this way with 384 numbers instead of two, reading at most 256 tokens and cutting off the rest. The question and the chunks must be embedded by the same model so the vectors line up.
A vector store keeps every chunk next to its embedding and finds the stored vectors closest to a given one. While production systems use a vector database like PostgreSQL with pgvector, a plain Java list works for a few hundred chunks.
Cosine similarity compares two embeddings and returns one score between -1 and 1, where 1 means the same meaning, 0 means unrelated, and -1 means opposite. It is calculated by multiplying the two arrays position by position, adding the results, and dividing by the magnitude of each array. This ensures that a long text and a short text with the same meaning still score high. Higher scores mean closer meanings, which is useful for ranking chunks.
Top-k is the number of best-scoring chunks kept from the search. A small k keeps the prompt short but can miss the answer, while a large k adds unrelated text. The context window is the maximum number of tokens the LLM reads in one call, meaning the instruction, question, and all top-k chunks must fit within it.
Building a Minimal RAG in Plain Java
The Recipe Box example can be built as a small Maven project using LangChain4j's in-process embedding model, meaning the chunking, vector store, similarity search, and prompt are all custom code.
Step 1: Create the Maven Project
The project places classes in the com.howtodoinjava.rag package and recipes in src/main/resources. It requires the langchain4j-embeddings-all-minilm-l6-v2 dependency, which holds the model file and runs it inside the JVM without an API key, and also brings in Jackson for JSON parsing.
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
         xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
         xsi:schemaLocation="http://maven.apache.org/POM/4.0.0
                             https://maven.apache.org/xsd/maven-4.0.0.xsd">
  <modelVersion>4.0.0</modelVersion>

  <groupId>com.howtodoinjava</groupId>
  <artifactId>rag-explained</artifactId>
  <version>1.0</version>

  <properties>
    <maven.compiler.release>17</maven.compiler.release>
    <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
    <exec.mainClass>com.howtodoinjava.rag.RecipeBoxRag</exec.mainClass>
  </properties>

  <dependencies>
    <!-- Offline embedding model: all-MiniLM-L6-v2 runs inside the JVM, no API key -->
    <dependency>
      <groupId>dev.langchain4j</groupId>
      <artifactId>langchain4j-embeddings-all-minilm-l6-v2</artifactId>
      <version>1.22.0-beta32</version>
    </dependency>
  </dependencies>

  <build>
    <plugins>
      <plugin>
        <groupId>org.apache.maven.plugins</groupId>
        <artifactId>maven-compiler-plugin</artifactId>
        <version>3.16.0</version>
      </plugin>
      <plugin>
        <groupId>org.codehaus.mojo</groupId>
        <artifactId>exec-maven-plugin</artifactId>
        <version>3.6.4</version>
      </plugin>
    </plugins>
  </build>
</project>
The first build downloads about 190 MB for the model and its runtime.
Step 2: Add the Recipe Documents
Four plain text files are added, each with a title on the first line, followed by paragraphs for ingredients, method, and serving notes. The lemon cake file looks like this:
Nani's Lemon Semolina Cake

Ingredients: 1 cup fine semolina, 3/4 cup sugar, 1 cup yogurt, 1/2 cup
melted butter, zest of 2 lemons, 1 teaspoon baking powder and a pinch of
cardamom.

Method: Mix the semolina, sugar and yogurt, and let the batter rest for
20 minutes so the semolina softens. Stir in the butter, zest, cardamom
and baking powder. Bake at 170 C for 38 minutes in a 9-inch tin.

Serving: Pour warm lemon syrup over the cake while it is still hot. The
cake keeps for 3 days in an airtight box at room temperature.
The other files, including a banana bread recipe that also mentions baking in a tin, are available on GitHub.
Step 3: Create the Vector Store
The vector store is a list of entries holding a chunk and its embedding. Its search() method scores every entry against the question's embedding using cosine similarity, sorts them, and keeps the top-k.
package com.howtodoinjava.rag;

import java.util.ArrayList;
import java.util.Comparator;
import java.util.List;

/**
 * A vector store kept in a plain list: every chunk is saved next to its embedding,
 * and a search compares the question's embedding with all of them.
 */
public class InMemoryVectorStore {

    public record Entry(String chunk, float[] embedding) {
    }

    public record Match(String chunk, double score) {
    }

    private final List<Entry> entries = new ArrayList<>();

    public void add(String chunk, float[] embedding) {
        entries.add(new Entry(chunk, embedding));
    }

    public int size() {
        return entries.size();
    }

    /** Similarity search: score every stored chunk and keep the top-k. */
    public List<Match> search(float[] questionEmbedding, int topK) {
        return entries.stream()
                .map(e -> new Match(e.chunk(), cosineSimilarity(questionEmbedding,
                        e.embedding())))
                .sorted(Comparator.comparingDouble(Match::score).reversed())
                .limit(topK)
                .toList();
    }

    /** Cosine similarity = (A . B) / (|A| * |B|), a number from -1 to 1. */
    static double cosineSimilarity(float[] a, float[] b) {
        double dot = 0;
        double normA = 0;
        double normB = 0;
        for (int i = 0; i < a.length; i++) {
            dot += a[i] * b[i];
            normA += a[i] * a[i];
            normB += b[i] * b[i];
        }
        return dot / (Math.sqrt(normA) * Math.sqrt(normB));
    }
}
Step 4: Create the Ollama Client
Ollama runs open models locally behind an HTTP API on port 11434. The model is downloaded with one command, taking about 400 MB:
ollama pull qwen2.5:0.5bThe client sends the prompt to Ollama's /api/chat endpoint and returns the text answer.
package com.howtodoinjava.rag;

import java.io.IOException;
import java.net.URI;
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpResponse;
import java.time.Duration;
import java.util.List;
import java.util.Map;

import com.fasterxml.jackson.databind.JsonNode;
import com.fasterxml.jackson.databind.ObjectMapper;

/**
 * Sends one prompt to a local Ollama server and returns the model's text answer.
 * This is the "generate" phase of RAG; the class knows nothing about retrieval.
 */
public class OllamaClient {

    /** The same instruction for every call, with or without RAG. */
    static final String SYSTEM_MESSAGE =
            "You are a cooking assistant. Answer in one or two sentences.";

    private static final ObjectMapper JSON = new ObjectMapper();

    private final HttpClient http = HttpClient.newBuilder()
            .connectTimeout(Duration.ofSeconds(5))
            .build();
    private final String baseUrl;
    private final String model;

    public OllamaClient(String baseUrl, String model) {
        this.baseUrl = baseUrl;
        this.model = model;
    }

    /** Reads OLLAMA_URL and OLLAMA_MODEL, with the Ollama defaults as fallback. */
    public static OllamaClient fromEnvironment() {
        String url = System.getenv()
                .getOrDefault("OLLAMA_URL", "http://localhost:11434");
        String model = System.getenv().getOrDefault("OLLAMA_MODEL", "qwen2.5:0.5b");
        return new OllamaClient(url, model);
    }

    public String generate(String prompt) throws IOException, InterruptedException {
        Map<String, Object> body = Map.of(
                "model", model,
                "stream", false,
                "messages", List.of(
                        Map.of("role", "system", "content", SYSTEM_MESSAGE),
                        Map.of("role", "user", "content", prompt)),
                // temperature 0 and a fixed seed give the same answer on every run;
                // num_predict caps the answer length in tokens
                "options", Map.of("temperature", 0, "seed", 42, "num_predict", 200));

        HttpRequest request = HttpRequest.newBuilder(URI.create(baseUrl + "/api/chat"))
                .timeout(Duration.ofMinutes(2))
                .header("Content-Type", "application/json")
                .POST(HttpRequest.BodyPublishers.ofString(JSON.writeValueAsString(body)))
                .build();

        HttpResponse<String> response =
                http.send(request, HttpResponse.BodyHandlers.ofString());
        if (response.statusCode() != 200) {
            throw new IOException("Ollama returned " + response.statusCode()
                    + ": " + response.body());
        }
        JsonNode json = JSON.readTree(response.body());
        return json.path("message").path("content").asText().strip();
    }
}
Temperature 0 and a fixed seed ensure consistent answers, while num_predict caps the answer at 200 tokens. The AskWithoutRag class tests the client and produces the wrong answer shown earlier.
package com.howtodoinjava.rag;

/**
 * Asks the model about a private recipe with no retrieved text in the prompt.
 * The model has never seen our Recipe Box, so it can only guess.
 */
public class AskWithoutRag {

    public static void main(String[] args) throws Exception {
        String question = "How long do I bake Nani's Lemon Semolina Cake, "
                + "and at what temperature?";

        OllamaClient llm = OllamaClient.fromEnvironment();
        String answer = llm.generate(question);

        System.out.println("Question: " + question);
        System.out.println("Answer:");
        System.out.println(answer);
    }
}
Step 5: Run Index, Retrieve and Generate
The RecipeBoxRag class runs the three phases. The chunk() method creates one chunk per paragraph, starting each with the recipe title to make it findable. The buildPrompt() method places the question before the chunks to prevent the model from focusing on the wrong details.
package com.howtodoinjava.rag;

import java.io.IOException;
import java.io.InputStream;
import java.io.UncheckedIOException;
import java.net.ConnectException;
import java.nio.charset.StandardCharsets;
import java.util.ArrayList;
import java.util.List;
import java.util.Locale;

import dev.langchain4j.model.embedding.EmbeddingModel;
import dev.langchain4j.model.embedding.onnx.allminilml6v2.AllMiniLmL6V2EmbeddingModel;

/**
 * A minimal RAG pipeline for a private Recipe Box: index, retrieve, generate.
 */
public class RecipeBoxRag {

    static final List<String> RECIPE_FILES = List.of(
            "lemon-semolina-cake.txt",
            "banana-walnut-bread.txt",
            "tomato-rasam.txt",
            "sunday-pancakes.txt");

    static final int TOP_K = 2;

    public static void main(String[] args) throws Exception {
        String question = args.length > 0
                ? String.join(" ", args)
                : "How long do I bake Nani's Lemon Semolina Cake, "
                        + "and at what temperature?";

        // embedding model: runs inside the JVM, no API key, 384 numbers per text
        EmbeddingModel embeddingModel = new AllMiniLmL6V2EmbeddingModel();
        InMemoryVectorStore store = new InMemoryVectorStore();

        // Phase 1: index. Chunk every document, embed every chunk, store both.
        for (String file : RECIPE_FILES) {
            for (String chunk : chunk(loadRecipe(file))) {
                float[] vector = embeddingModel.embed(chunk).content().vector();
                store.add(chunk, vector);
            }
        }
        System.out.println("Indexed " + store.size() + " chunks");

        // Phase 2: retrieve. Embed the question, then run a similarity search.
        float[] questionVector = embeddingModel.embed(question).content().vector();
        List<InMemoryVectorStore.Match> matches = store.search(questionVector, TOP_K);

        System.out.println("Question: " + question);
        System.out.println("Top-" + TOP_K + " chunks:");
        for (InMemoryVectorStore.Match match : matches) {
            System.out.printf(Locale.ROOT, "  %.3f  %s%n", match.score(),
                    ConsoleFormat.shorten(match.chunk()));
        }

        // Phase 3: generate. Put the retrieved text into the prompt, then call the LLM.
        String prompt = buildPrompt(question, matches);
        System.out.println();
        System.out.println("Prompt sent to the model:");
        System.out.println(prompt);
        System.out.println();
        System.out.println("Answer:");
        System.out.println(ConsoleFormat.wrap(generateOrExplain(prompt)));
    }

    /** Splits a recipe into chunks: one per paragraph, each starting with the title. */
    static List<String> chunk(String recipe) {
        String[] paragraphs = recipe.strip().split("\\n\\s*\\n");
        String title = paragraphs[0].strip();
        List<String> chunks = new ArrayList<>();
        for (int i = 1; i < paragraphs.length; i++) {
            chunks.add(title + "\n" + paragraphs[i].strip());
        }
        return chunks;
    }

    /** The augmented prompt: instruction, question, then the retrieved chunks. */
    static String buildPrompt(String question, List<InMemoryVectorStore.Match> matches) {
        List<String> chunks = matches.stream()
                .map(InMemoryVectorStore.Match::chunk)
                .toList();
        return """
                Answer the question using only the context below.
                If the context does not contain the answer,
                say "The Recipe Box does not say."

                Question: %s

                Context:
                %s""".formatted(question, String.join("\n\n", chunks));
    }

    static String generateOrExplain(String prompt) throws InterruptedException {
        try {
            return OllamaClient.fromEnvironment().generate(prompt);
        } catch (ConnectException e) {
            return "(no Ollama server found; start one to see the generated answer)";
        } catch (IOException e) {
            return "(Ollama call failed: " + e.getMessage() + ")";
        }
    }

    static String loadRecipe(String file) {
        String path = "/recipes/" + file;
        try (InputStream in = RecipeBoxRag.class.getResourceAsStream(path)) {
            if (in == null) {
                throw new IllegalStateException("Recipe not found: " + file);
            }
            return new String(in.readAllBytes(), StandardCharsets.UTF_8);
        } catch (IOException e) {
            throw new UncheckedIOException(e);
        }
    }
}
Step 6: Run the Program
With Ollama running, the program is executed via Maven:
mvn compile exec:javaThe output shows the retrieved chunks, the prompt, and the correct answer:
Indexed 12 chunks
Question: How long do I bake Nani's Lemon Semolina Cake, and at what temperature?
Top-2 chunks:
  0.840  Nani's Lemon Semolina Cake | Method: Mix the semolina, su...
  0.788  Nani's Lemon Semolina Cake | Serving: Pour warm lemon syr...

Prompt sent to the model:
Answer the question using only the context below.
If the context does not contain the answer,
say "The Recipe Box does not say."

Question: How long do I bake Nani's Lemon Semolina Cake, and at what temperature?

Context:
Nani's Lemon Semolina Cake
Method: Mix the semolina, sugar and yogurt, and let the batter rest for
20 minutes so the semolina softens. Stir in the butter, zest, cardamom
and baking powder. Bake at 170 C for 38 minutes in a 9-inch tin.

Nani's Lemon Semolina Cake
Serving: Pour warm lemon syrup over the cake while it is still hot. The
cake keeps for 3 days in an airtight box at room temperature.

Answer:
  To bake Nani's Lemon Semolina Cake, you should bake it at 170 C for 38
  minutes.
Common RAG Failures and How to Fix Them
RAG can fail if the search returns the wrong chunks or if the model adds facts not present in the chunks. The RagTrap class demonstrates both issues.
Retrieving the Wrong Chunk
If a chunker splits recipes into paragraphs but drops the title, the search can fail.
/** The broken chunker: one chunk per paragraph, and the title is dropped. */
static List<String> chunkWithoutTitle() {
    List<String> chunks = new ArrayList<>();
    for (String file : RecipeBoxRag.RECIPE_FILES) {
        String recipe = RecipeBoxRag.loadRecipe(file);
        String[] paragraphs = recipe.strip().split("\\n\\s*\\n");
        for (int i = 1; i < paragraphs.length; i++) {
            chunks.add(paragraphs[i].strip());
        }
    }
    return chunks;
}
When asking about the lemon cake with top-1 retrieval, the results differ based on the chunking method:
Trap 1, question: How long do I bake the lemon cake, and at what temperature?
Chunks WITHOUT the title:
  0.687  Serving: Pour warm lemon syrup over the cake while it is ...
  Answer: To bake the lemon cake, you should pour warm lemon syrup over the
  cake while it is still hot. The cake keeps for 3 days in an airtight box
  at room temperature.
Chunks WITH the title:
  0.585  Nani's Lemon Semolina Cake | Method: Mix the semolina, su...
  Answer: To bake the lemon cake, you should bake it at 170 C for 38
minutes.| Rank | Without the title | Score | With the title | Score |
|---|---|---|---|---|
| 1st | Lemon cake, serving notes | 0.687 | Lemon cake, method (has the answer) | 0.585 |
| 2nd | Lemon cake, method (has the answer) | 0.432 | Lemon cake, serving notes | 0.542 |
| 3rd | Banana bread, method | 0.413 | Lemon cake, ingredients | 0.368 |
Without the title, the method paragraph never mentions "lemon" or "cake," causing the serving notes to rank first and leading to a wrong answer. Every chunk should carry the name of the document it came from, stay on one topic, and fit under the embedding model's token limit.
Answering Beyond the Retrieved Text
When asked "Can I freeze Nani's Lemon Semolina Cake?", the recipe does not provide an answer. A loose prompt allows the model to invent one.
/** The broken prompt: it lets the model add what it "knows" to the context. */
static String loosePrompt(String question, List<InMemoryVectorStore.Match> matches) {
    List<String> chunks = matches.stream()
            .map(InMemoryVectorStore.Match::chunk)
            .toList();
    return """
            Use the context below to help you answer.

            Question: %s

            Context:
            %s""".formatted(question, String.join("\n\n", chunks));
}
Trap 2, question: Can I freeze Nani's Lemon Semolina Cake?
Loose prompt answer:
Yes, you can freeze Nani's Lemon Semolina Cake. The cake keeps for 3 days
in an airtight box at room temperature.
Strict prompt answer:
The Recipe Box does not say.The loose prompt causes the model to say yes and mix in a real sentence from the chunk. The strict prompt tells the model to answer only from the context and provides an exact sentence for missing answers.
Framework Alternatives
In an application, frameworks provide these components. LangChain4j offers InMemoryEmbeddingStore and EmbeddingStoreContentRetriever for similarity searches. Spring AI builds the same pipeline using its EmbeddingModel and VectorStore.
Capabilities and Comparisons
RAG differs from fine-tuning by placing documents in the prompt at question time, whereas fine-tuning changes the model's weights through further training. A changed document takes effect in RAG as soon as it is re-indexed. While a list in memory works for small document sets, a vector database becomes useful when the index must survive a restart or when comparing every vector gets too slow. The pipeline can run fully offline after the initial build; the all-MiniLM-L6-v2 model runs inside the JVM, and Ollama runs the LLM locally. Document loaders and parsers allow the use of PDF or Word files by turning them into plain text first. Finally, RAG reduces but does not stop AI hallucinations, as a model can still add facts that are not in the retrieved text.
Optimizing Local RAG Performance
A complete RAG pipeline indexes documents once by chunking, embedding, and storing them, then retrieves the closest chunks for each question to generate an answer. In the Recipe Box example, the 0.5B-parameter model corrected its initial guess of 180 C for 30 minutes to the accurate 170 C for 38 minutes after a successful search. To prevent retrieval failures, every chunk should carry the name of its source document, ensuring that sections like method paragraphs are not outranked by serving notes. Additionally, instructing the model to answer strictly from the provided context helps maintain accuracy.
This article was written by AI from reporting by howtodoinjava.com.